Automated data science
Auto Data Analyst
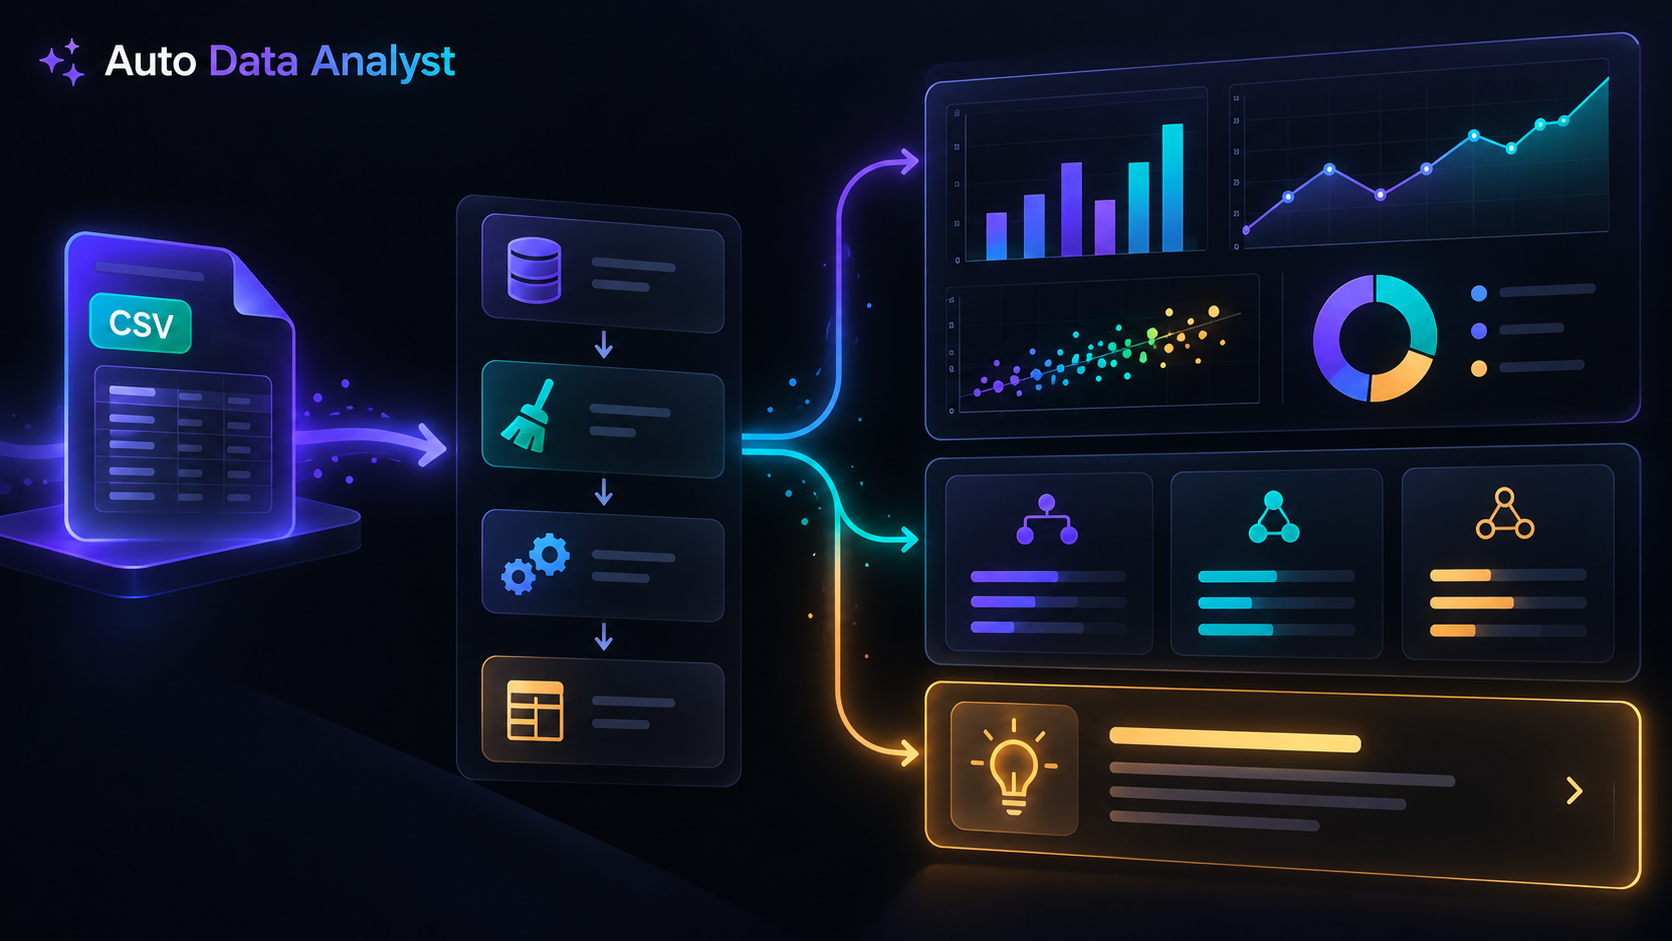
Upload a CSV and move from raw data to cleaning, exploration, model comparison, and plain-language recommendations through one guided interface.
Interactive preview
Try a demo
Analyze a small CSV. This is a small browser-only illustration, not the full application. AI responses are scripted; model and desktop features are not running here. Inputs stay on this page and reset when you reload.
Result
Ready. Change the sample and run the demo.
Explore the real workflow
Upload a CSV or a set of related datasets.
The full app's capabilities and requirements are described below.
What it is for
Upload a CSV and move from raw data to cleaning, exploration, model comparison, and plain-language recommendations through one guided interface.
Exploratory analysis and baseline modeling require many repetitive decisions before the interesting work begins. Auto Data Analyst makes those steps visible and accessible to people who do not live in notebooks.
- Understand a new CSV
- Review distributions, column quality, and relationships before choosing a model.
- Compare a baseline
- Evaluate candidate algorithms with cross-validation and inspect the resulting metrics.
- Explain an analysis
- Connect plots and recommendations to the input data and the pipeline decisions.
Get started
Open Auto Data Analyst, upload a representative CSV, and inspect column types and proposed cleaning. Choose the analysis target only after checking the dataset and pipeline.
- A browser and a CSV dataset you are permitted to upload.
- A clearly defined target when running supervised model comparison.
- Manual review for leakage, sensitive fields, and unusually structured data.
Features and workflow
- Automated cleaning
- Detect common quality problems and prepare an analysis-ready dataset.
- Exploratory analysis
- Generate distributions, relationships, summaries, and visual diagnostics from an uploaded CSV.
- Model comparison
- Train and compare more than 15 candidate algorithms with cross-validation.
- Ensembling
- Evaluate boosted models including XGBoost, LightGBM, and CatBoost alongside standard baselines.
- Editable pipeline
- Review and adjust the generated workflow instead of accepting a black-box result.
- Data Q&A
- Ask questions over the uploaded data and receive explanations tied to the analysis.
- Upload a CSV or a set of related datasets.
- Review detected columns, quality issues, and proposed cleaning.
- Choose the target and adjust the guided pipeline when needed.
- Run exploratory analysis and cross-validated model comparison.
- Inspect metrics, plots, and plain-language recommendations before exporting results.
Architecture
The deployed application uses Flask with Gunicorn, Python data-processing and machine-learning libraries, and Docker. A Streamlit interface belongs to the historical prototype.
Privacy and limitations
Uploaded data is processed by the self-hosted service. Automatic cleaning and model ranking are starting points: leakage, target definition, fairness, causal claims, and business consequences still require human review.
Status
Live as a self-hosted web application. Large or unusually structured datasets may need manual preprocessing beyond the guided defaults.
- Availability
- Live web app
- Input
- CSV datasets
- Models
- 15+ candidates
- Audience
- Guided analysis
Questions
What files should I start with?
Start with a CSV whose columns and intended analysis you understand. Complex or unusual data may need preprocessing.
Is the highest-scoring model always best?
No. Leakage, the evaluation split, business costs, interpretability, and data quality can matter more than a single score.
Can I review the cleaning?
The guided workflow exposes preparation and pipeline choices. Review them before accepting the resulting analysis.